A Kafka consumer that keeps up with the surge
A service consumes a Kafka topic and feeds Elasticsearch. Under a surge, its lag only grew.
- in consumption and in how fast data reaches search, under the same CPU-based HPA
- 4.5 to 5×
The problem
Batches of up to 2,000, worked 100 messages at a time, each with its own query and its own send. Two calls per message bound the CPU at a low throughput: the HPA added instances, only one per partition consumed, and the lag kept growing.
What I changed
One query with the keys of the whole batch, and output in chunks of 500. Calls became per batch instead of per message, and each instance got slack on the same CPU: the ones the HPA adds drain the queue.
How it works
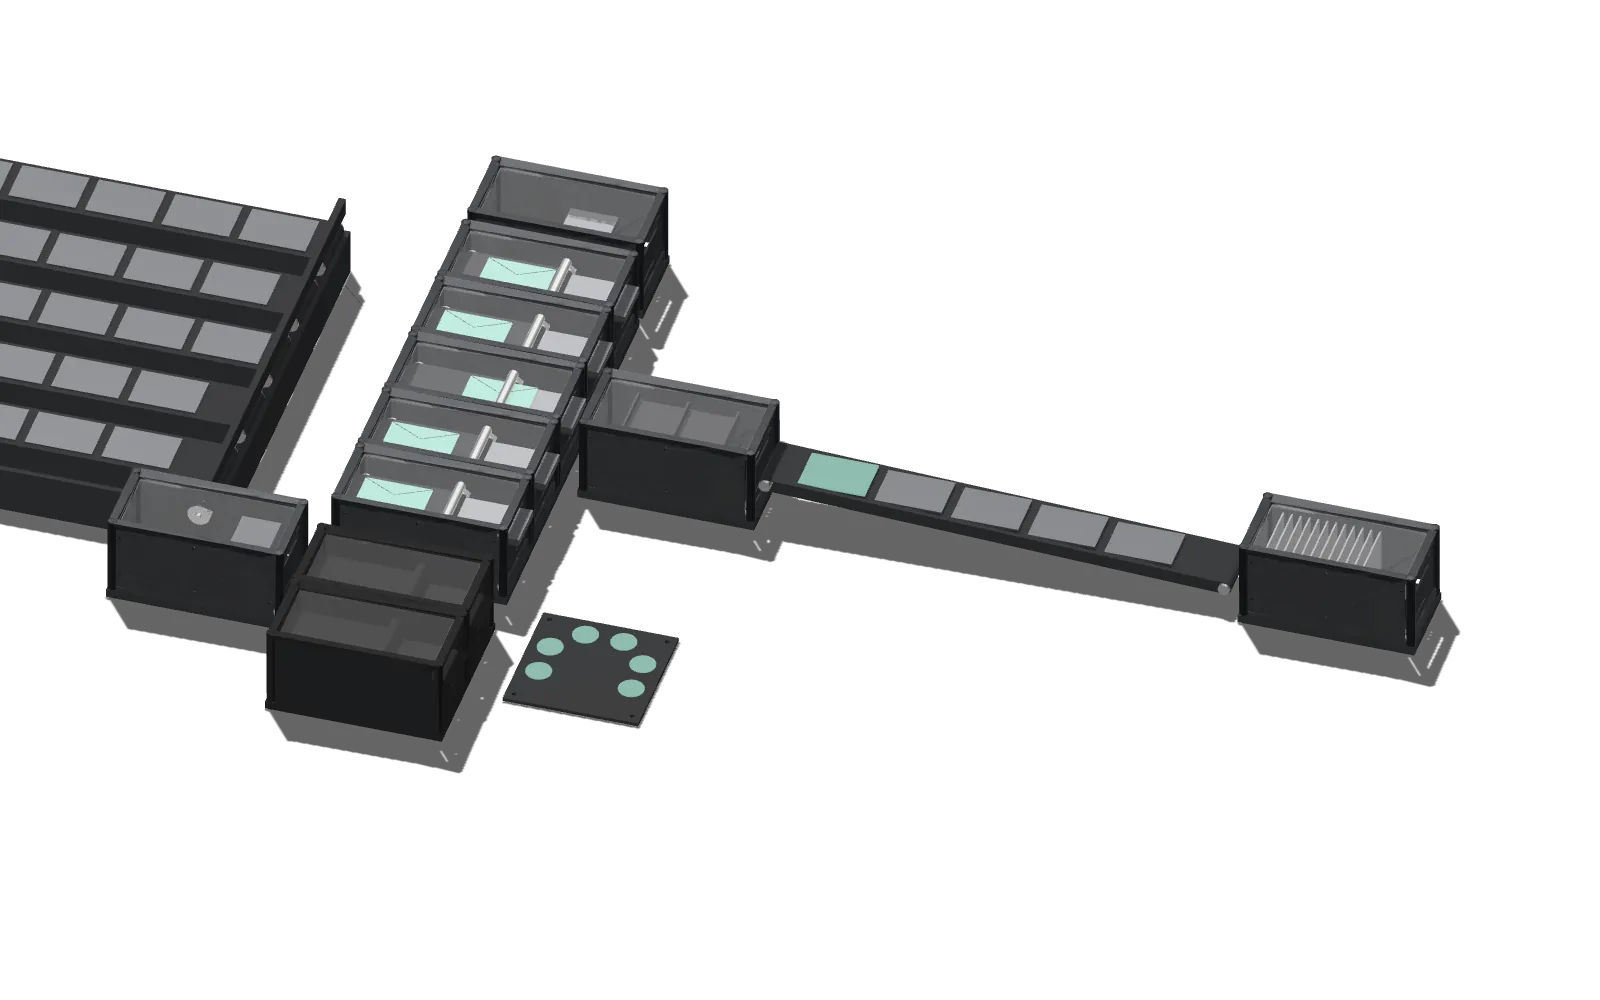
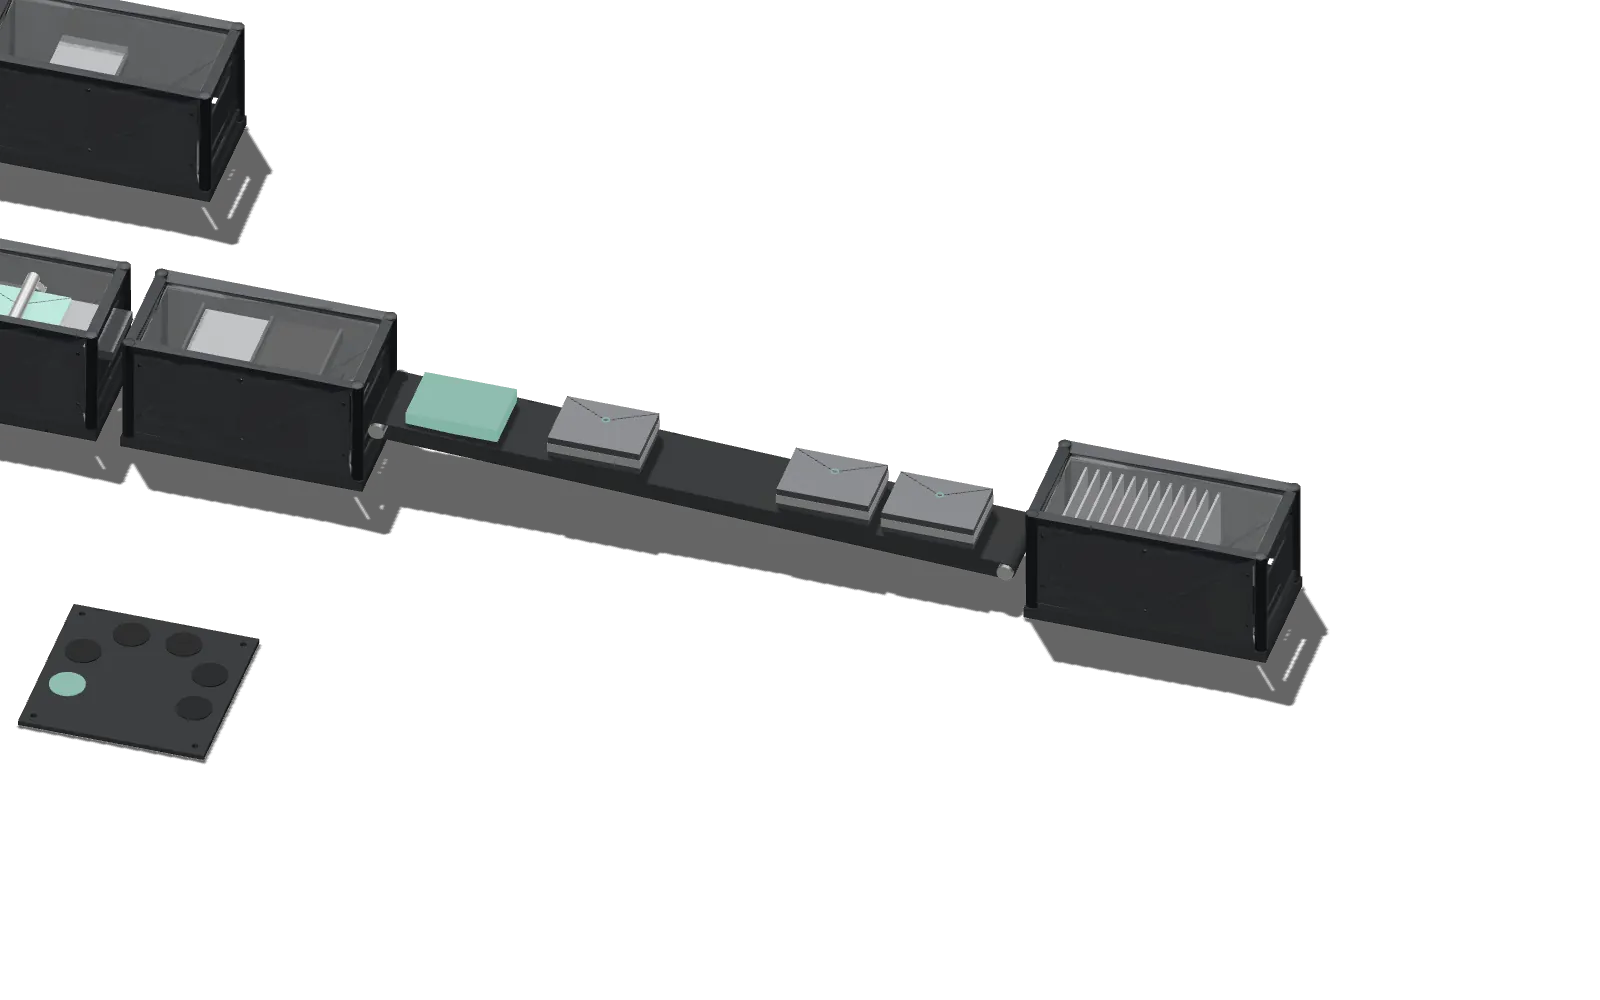
The parameters
- Max batch (B)
- 2,000 msg
- Concurrency, before (C)
- 100 msg
- Chunk, after (S)
- 500 msg
- Distinct keys (N)
- 5,000 keys
- Query, fixed cost (q₀)
- 2 ms
- Query, per key (q_k)
- 0.05 ms
- Processing (m)
- 0.4 ms
- Send (c)
- 3 ms
- Commit (k_c)
- 2 ms
- CPU per call (κ)
- 0.85 ms
- Cores (n)
- 1 core
- Partitions (P)
- 5 partitions
- HPA CPU target (u*)
- 70 %
- Throughput per instance at full load, before and after
- 476 → 2,176 msg/s
The time of a batch of b messages
batch   b = min(fetch, B)
before  ℓ = q₀ + q_k + m + c
        τ(b) = max(⌈b/C⌉·ℓ, b·(m + 2κ)/n) + k_c
after   K(b) = N·(1 − (1 − 1/N)^b)
        τ(b) = q₀ + q_k·K(b) + m·b + ⌈b/S⌉·c + k_c
Got a consumer that can’t keep up with its surge? Let’s talk about it.